CASE   № 04
PERIOD   2026
LOCATION   Remote · UTC+10

A document harvesting and recognition pipeline

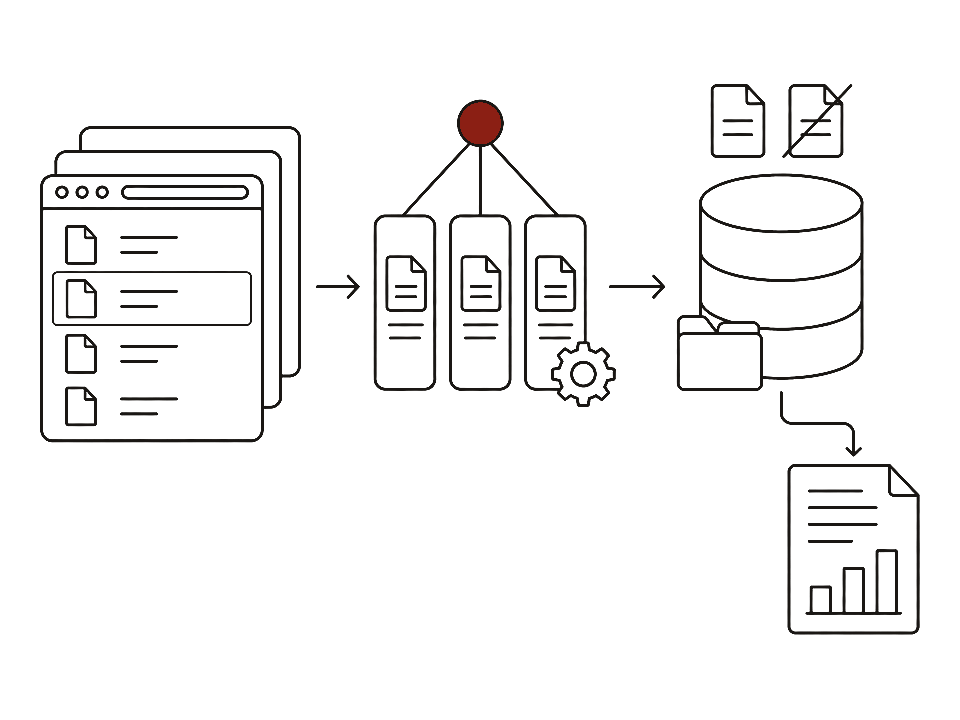
A monorepo of a dozen CLI tools and an admin panel: crawling start URLs, finding and downloading files, hash-based de-duplication, upload to object storage, batch recognition through a language model and dispatch of the results. A scheduled job queue, one shared database schema, build and deploy from CI. The system runs in production and is closed to outside access.

A document harvesting and recognition pipeline
FIG. 04 — Processing pipeline

Collecting documents from public sources and turning them into structured data — a job that cannot be done by hand.

A monorepo of a dozen tools and an admin panel: crawling URLs, downloading files, hash-based de-duplication, object storage, batch recognition by a language model and dispatch of the results. A scheduled job queue drives all of it.

The full write-up is still being written — this is the short version for now. Happy to walk you through the details.

Discuss a similar project →